Level 2
Oct 26, 2026 6:59 AM UTC
Question

GraphQl endpoint is not working on aem author instance

Hi,

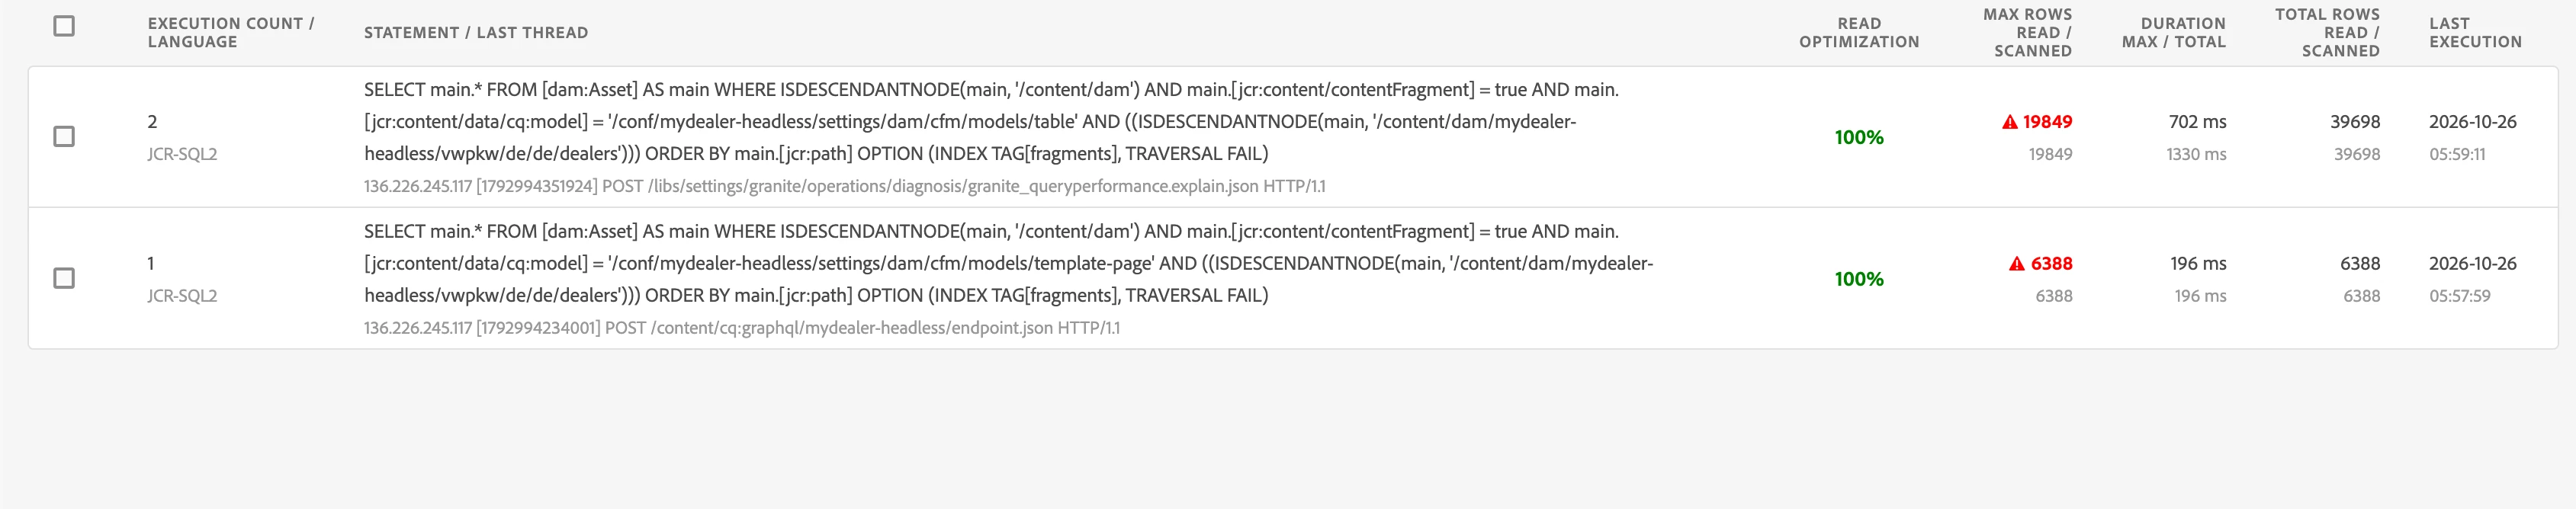
Recently, we have started seeing an issue with GraphQL queries in AEM Author across multiple environments. When executing grapgql queries, we receive a “Failed to load the GraphQL endpoint” error, even though the GraphQL endpoint appears to be configured correctly.

For some Content Fragment Models, we are also seeing traversal-related failures.

This behavior started after our recent deployment, where we migrated/updated the indexes as part of the simplified index management approach. However, we compared the previous and current index definitions and couldn't identify any significant changes that would explain the issue.

A few observations:

  • The issue occurs only for one specific Content Fragment folder.
  • Other folders containing Content Fragments based on the same model are able to fetch data successfully.
  • The affected folder contains a comparatively larger number of Content Fragments, so we are unsure whether the issue is related to indexing/query traversal or the volume of content in that folder.
  • The same queries were working correctly before the index migration, irrespective of the number of Content Fragments in the folder.
  • In some cases, it appears to work on Publish, but this could potentially be due to cached responses/content.
  • The GraphQL endpoint itself is already present and configured correctly.

Has anyone encountered similar GraphQL/traversal issues after migrating to simplified index management?

If the index definition and GraphQL endpoint configuration are correct, what else could cause the query to fail only for a particular Content Fragment folder? Could this be related to query traversal limits, index selection, stale/reindexing state, content volume, or the query not using the expected index?

Any suggestions on what we should validate next would be helpful.


4 replies

Level 2
Oct 26, 2026 10:57 AM UTC

​@khn ,

Can you confirm if you’re getting an error like this - https://medium.com/@bsaravanaprakash/aem-graphql-fa%C3%A7ade-patterns-building-wrappers-apis-around-aem-graphql-92f36f5a79d8 in your logs?

This should be the possible cause for the issue you’re facing where it is trying to traverse through a large set of nodes.

Two limits worth ruling out:

  1. Oak read limit. Queries that read more than 100,000 nodes are stopped with “The query read or traversed more than 100000 nodes”, reported even for index-backed Content Fragment queries. Check the author logs for that message when the failure happens.
  2. GraphQL filtering. Per Adobe’s GraphQL optimization doc, JCR-level filtering only applies to top-level fragments, and filtering or sorting on nested fragments can load a lot of fragments into memory. If the failing query does that, filter on top-level fields and use first/after pagination.

Hope this helps.

Regards,

Santhosh

Translate
khnAuthor
Level 2
Oct 26, 2026 12:15 PM UTC

Hi ​@social_portfolio81db , yes. I’m getting same error in logs.

Translate
Level 2
Oct 26, 2026 3:12 PM UTC

​@khn ,

Since you see “The query read or traversed more than 100000 nodes” in the logs, the query is hitting Oak’s read limit. That limit counts nodes read through an index too, so an index-backed query can still fail if the index returns too many candidates.

What I’d check first:

  1. Count the fragments of the failing model across /content/dam and compare that with the count inside the failing folder. The path filter may be applied after the index read, so the total could matter more than the folder size.
  2. Compare the deployed fragments index with the one in the AEM Content Fragment GraphQL index package, and confirm in Query Performance that the query still picks fragments.

If the query still can’t be kept under the limit, since it runs ad hoc from the GraphQL editor on author:

  • Filter on top-level fragment fields and add first/after pagination (or limit). Adobe’s GraphQL optimization doc says JCR-level filtering only applies to top-level fragments, and nested filtering or sorting can load many fragments.
  • Update the existing fragments for hybrid filtering, as described in the same doc.
  • In one community case, excluding a large unrelated folder from the index fixed the same error. Test that on a lower environment first, since it affects every query using that index.
  • If the index looks correct and reads still exceed the limit, raise it with Adobe Support.

Publish working is most likely cached responses, so I wouldn’t treat it as proof the query is fine.

If you can share the failing query’s explain output, it will be easier to narrow down.

Doc: https://experienceleague.adobe.com/fr/docs/experience-manager-cloud-service/content/headless/graphql-api/graphql-optimization

Regards,

Santhosh

Translate
sarav_prakash
Community Advisor
Community Advisor
Nov 3, 2026 1:33 AM UTC

Hi ​@khn , ​@social_portfolio81db ,

Thanks for referring to my article. Yes I ran into exact same problem. Here is how to solve:


  1. Confirm the traversal limit warnings first - Look for error.log entries like `org.apache.jackrabbit.oak.query.QueryImpl Traversed X nodes...query may be slow` and `java.lang.RuntimeException: java.util.concurrent.ExecutionException: ... query read more than 100000 nodes`
  2. Verify property index is fully rebuilt and active - After index migration, run a check at /libs/granite/operations/content/diagnosis/tool.html → Index Health Check. If the relevant damAssetLucene or custom index is still in reindexing state, queries against large datasets will either time out or traverse unindexed nodes.

  3. Use the Query Debugger to confirm index selection - Hit /libs/cq/search/content/querydebug.html and run the raw JCR-SQL2 or QueryBuilder equivalent of your GraphQL query (scoped to the affected folder path). The explain output will show you which index is actually selected. If it shows traverse instead of your expected index, the issue is index selection, not the GraphQL configuration.

Now above is NOT a fix. Only diagnose to confirm your issue. For long-term solution, refer to my Facade article. I followed facade 4 that transforms request and response.

This picture summarizes the approach 


Please share if any hiccups, I can help with more specific code examples. 

Translate